NVIDIA CMX
Public / vendorReported: 2H 2026Up to 5×vs “traditional storage” · baseline undisclosed
TECHNICAL BRIEF · VS NVIDIA CMX
Spilled KV cache is stored in G2.5, not recomputed. CMX and FX both fill this tier.
 GPU compute nodesXinyuanyi FX storage
480B long-context cold recovery · TTFT p50 · concurrency 16
8.6–20× vs recompute · R2 signed
10–30%time computingEven if you deploy a million GPUs, they actually compute maybe 10% to 30% of the time.
Joungho Kim · KAIST · often called the “father of HBM” · Dong-A Ilbo interview · July 2026, as reported
Public trend: compute vs memory
Bandwidth: HBM/DRAM are vendor peaks; G2.5 is R1 measured; local NVMe is PCIe Gen4 class; NFS is derived from R9 load time. GPU util 46.7%→62.8% is R1 (20 switches/hour).
KV cache spills down, no recompute RDMA-attached storage · prefetched back to HBM on hit
NVIDIA figures are vendor-public with no disclosed baseline. Every Xinyuanyi figure carries a report ID (R1–R9) and is open to re-verification. Not a disparagement or substitution claim. Kim’s 10–30% is a public industry judgment, not our measurement; 46.7%→62.8% is R1. NVIDIA CMX product page · NVIDIA Technical Blog · TechBang on Joungho Kim / Dong-A Ilbo · Epoch AI · Trends in ML hardware (2023)
The acceptance report is a free download. The two tables below are vendor-published specifications for comparing SKUs, not our measured throughput.
Multi-model token-supply capacity and acceptance report (external official V2.3)Full text is free. It is not one of the paid R1–R9 PDFs in the evidence library.
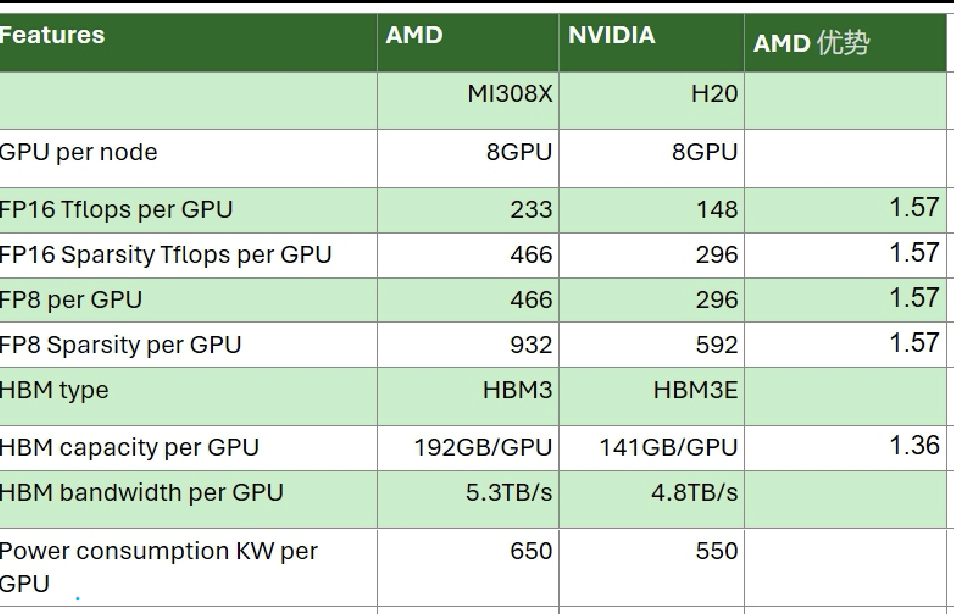
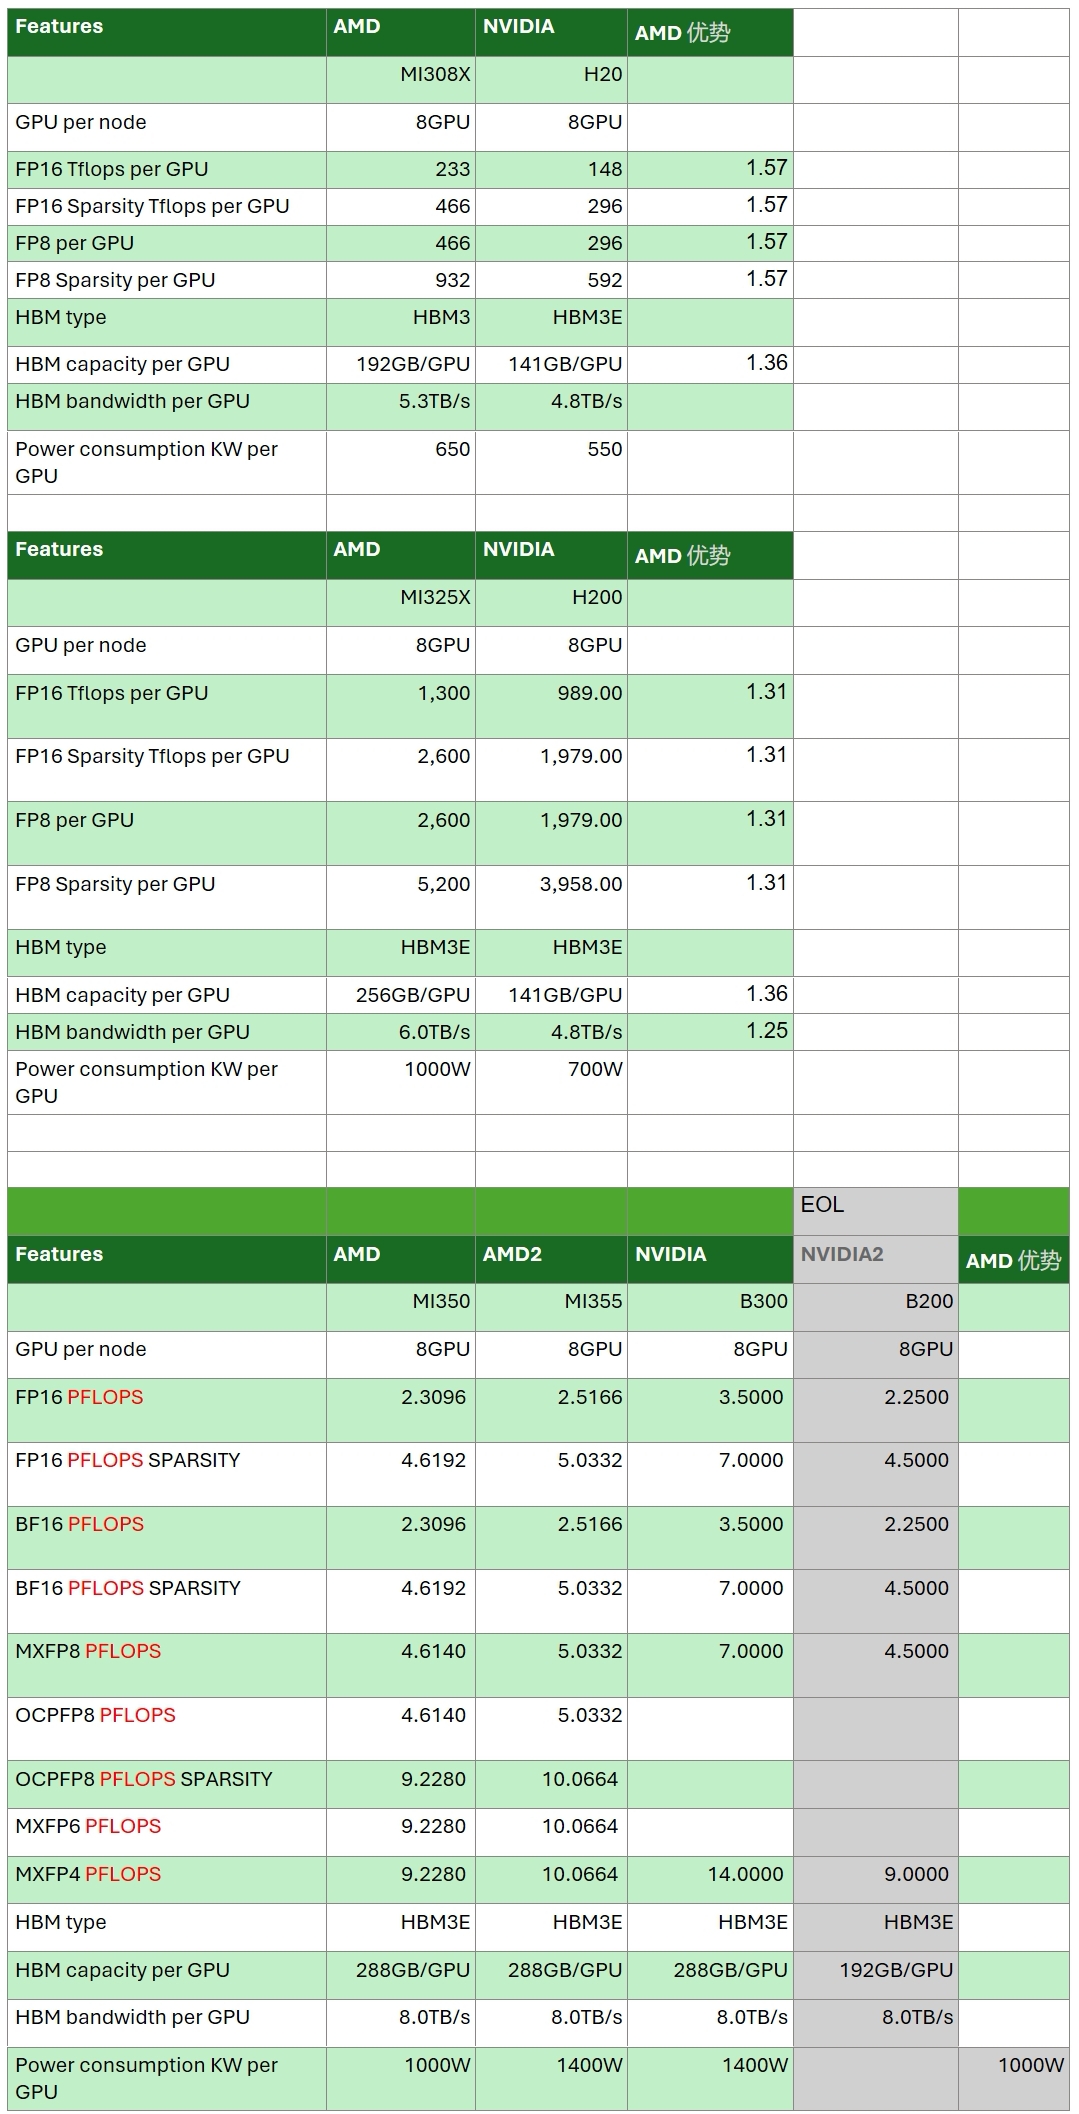
Vendor-published specifications. Not our measured throughput, and not a commercial multiple versus NVIDIA.